
Rendering, JavaScript and original content: how to make a website truly visible to AI crawlers, according to Nikki Halliwell
Here we are again with SEO Confidential, the column where we speak with some of the world’s leading SEO and GEO experts.
Today we’re talking about a topic that is becoming increasingly important for anyone working online and looking to be cited, mentioned and recommended by AI answer engines: rendering.
It may sound like a technical detail for developers, but in reality, it can determine whether your content is seen by AI crawlers or not. And if it isn’t seen, it simply doesn’t exist, no matter how valuable the content you have created may be.
Nikki Halliwell, an SEO expert with 10 years of experience in marketing and a specialisation in technical SEO and eCommerce, explains it all. Her approach is clear: use data to understand what is really happening and turn those insights into a practical action plan.
In this interview, Nikki explains why she believes rendering is one of the most overlooked aspects of SEO today, which technical issues can compromise the visibility of your content, and how to check, step by step, whether your website is truly accessible to AI systems.
Practical, concrete advice that you can put into action straight away.
Well, what more can we say? Just one thing: enjoy the interview!
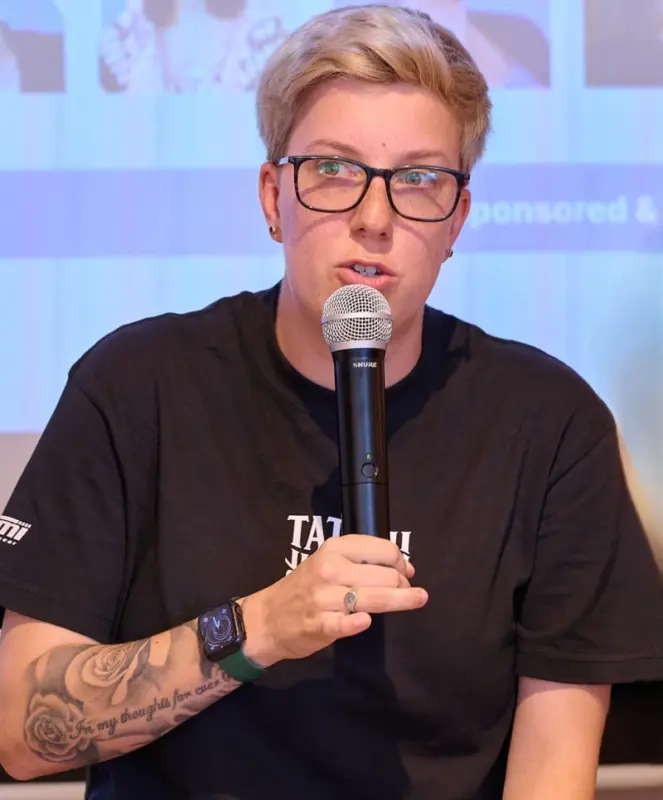
“Differentiation gets you noticed. Accessibility gets you found”, Nikki told us
Over the past few months, many new acronyms such as GEO, AEO and LLMO have emerged. How do you view this evolution? Do you think it represents a real change in the way SEO is done, or mainly a change in how it is described?
Honestly, it’s mostly the same discipline with a new label. Structured data, clear entity signals, well-organised content, technical accessibility. For most SEOs, none of this is new: we’ve been doing it for years.
What has really changed is the destination. Instead of having a crawler index a page and place it in a ranked list, we now have systems extracting portions of content from their context and using them to synthesise an answer.
This is a real mechanical difference, and it also changes some aspects of the technical work: you need to consider, for example, how content is broken into chunks, whether it can actually be retrieved, and how it gets cited.
So I’d say the same fundamental principles still apply, but they require some new ways of thinking. I’d be cautious of anyone presenting GEO as a completely new discipline that you need to learn from scratch.
With the growing amount of AI-generated content, what do you think will really make a brand stand out in AI-generated answers?
Having something that models can’t find on ten other pages that all say the same thing. It should be proprietary data, original research, a genuinely first-hand perspective or a concrete result you achieved yourself and can demonstrate.
If your content reads like a summary of what is already ranking in search results, you are competing to be one of many almost identical inputs. There is no reason for an AI system to choose you over the next page.
The second part is just as important: none of this matters if the content is not actually retrievable. I see brands with genuinely strong and differentiated content that never gets used because it is hidden behind JavaScript or poorly structured.
Differentiation gets you noticed. Accessibility gets you found.
Google AI Mode seems to favour comprehensive answers over simple pages optimised for a single keyword. How do you think this will change the way content is planned over the next few years?
I think we’ll move away from the keyword model and towards planning around an entire topic or topic cluster.
There may be a main query, but there will also be the follow-up questions people actually ask, the so-called query fan-out, comparisons and caveats. This means doing more research upfront to understand how a topic actually branches, and designing a content architecture that shows the relationships between these different pieces, rather than creating a series of thin pages, each targeting a slightly different long-tail variation.
It’s more work at the planning stage, but ultimately it means less duplication and fewer cannibalisation issues.
I also expect internal linking to become more important as a way of demonstrating topical coverage, rather than simply facilitating the crawling process.
Many people talk about the importance of first-hand experience and authority. What concrete signals should a website provide to be considered genuinely trustworthy by AI systems?
Anything that is difficult to fake. I’ve talked about original data, but you can also use real screenshots, case studies with concrete numbers, and identifiable authors with a verifiable track record elsewhere.
Consistency of entity information across the web is also important. What I mean is that your brand and your experts should present themselves consistently on your website, LinkedIn, in press coverage and in industry directories.
Freshness helps, but only when the updates are genuine and don’t simply involve changing the publication date.
Ultimately, content also needs to be accessible to crawlers and properly renderable, because a trust signal that a bot cannot see is of no use.
If you could give just one piece of advice to a company that wants to prepare for the evolution of Google AI Mode today, what would you invest in first and why?
Get your technical foundations right before doing anything else, and focus specifically on rendering.
I’ve analysed many websites with high-quality content and genuine expertise behind them that are effectively invisible to AI systems because the content only becomes available after JavaScript runs, or is hidden inside tabs that can only be accessed through JavaScript.
It’s frustrating because most AI crawlers don’t wait for content to render in the way Google does.
It doesn’t matter how strong your content strategy is: if the system serving your pages doesn’t allow that content to reach the systems trying to read it, all that work can end up being wasted.
In a recent article, you argue that rendering is becoming a decisive factor for visibility in AI systems. Do you think this is now one of the most overlooked technical aspects of SEO among companies and SEO professionals? Why?
I think it is. Most SEO discussions are still focused on content and keywords, while rendering audits tend to fall into the gap between SEO and development teams, especially in companies managing these activities in-house.
In the end, it becomes an area that nobody really takes ownership of, so the problem doesn’t get fixed.
There is another aspect to this: in the past, this problem was more easily tolerated. Google has been waiting for pages to render for years. As a result, many websites have been able to quietly live with slow or incomplete client-side rendering without ever realising the true cost.
AI crawlers generally don’t have the same patience and many of them cannot even execute JavaScript, even if they wanted to.
So a problem that used to remain invisible can now directly translate into lost visibility elsewhere, while most teams haven’t started looking for it yet.
And yet, many websites still rely heavily on JavaScript. What development mistakes do you most often see compromising the ability of search engines and AI systems to properly understand content?
The main problem is content that only exists after JavaScript runs, with nothing meaningful in the initial HTML.
Another example is infinite scrolling without a paginated alternative. For many crawlers, anything beyond the initial page load effectively doesn’t exist.
I also see content that is only loaded after a user interaction, such as clicking to expand a section. That content is never present in the DOM for a bot that doesn’t simulate clicks.
It is also worth checking that your robots.txt file isn’t blocking the JavaScript and CSS files needed to render the page correctly. It’s an easy mistake to overlook, and I still see it regularly.
Underneath most of these problems is the same issue: content delivery that depends on JavaScript, rather than using JavaScript to enhance content that is already present on the page.
What technical checks should a company carry out today to understand whether its website is genuinely readable and usable by AI systems?
I would start with Google Search Console’s URL Inspection tool and compare the rendered HTML it shows with the page’s raw source code. If there is a significant difference, that means the content depends on rendering in order to be displayed.
Try retrieving a page without executing JavaScript, as a basic scraper would, and check what content is actually there.
Also check page weight and loading times with PageSpeed Insights. Pages that are heavier or slower to render are more likely to time out for AI crawlers.
You should also validate your structured data and check that your robots.txt file and robots meta tags actually allow access to the AI crawlers from which you want visibility. Many websites and CDNs block them by default without the site owner realising it.
If you have access to log files, also analyse how these bots are actually behaving on your site rather than making assumptions. This is where the most concrete data lies, and having access to this information is becoming increasingly important.
The risk of model collapse, where AI models end up training primarily on content generated by other AI systems, is being discussed more and more. How real do you think this risk is, and what consequences could it have for the quality of information online?
I think it’s a long-term concern rather than an immediate crisis. The risk isn’t that models suddenly stop working, but that we see a gradual homogenisation, where the same patterns are repeated and reinforced while genuinely original thinking gets lost in the noise.
From a practical perspective, for anyone producing content, this means that using original data and first-hand experience becomes more valuable, not less, because this is material that isn’t already circulating online in hundreds of rewritten versions.
Do you think AI systems currently have a bias towards AI-generated content? If so, how can we prevent this from impoverishing the web?
I wouldn’t describe it as deliberate bias so much as a structural tendency. AI-generated content tends to be more predictable and organised according to more uniform structures, which makes it easier to analyse and synthesise. There is therefore a risk that pattern matching favours the average, formulaic piece over something distinctive with a genuine point of view.
To counter this trend, we need to focus on what gets rewarded. Platforms and search engines need to continue prioritising genuinely original and verifiable sources and first-hand data over content that is simply well structured. At the same time, publishers need to avoid flattening their own voice in order to make their content more “optimisable.”
If originality ends up being penalised, we risk losing precisely what makes content genuinely valuable.
If the web became saturated with AI-generated content, would models still have enough original knowledge to learn from, or would they gradually become worse?
It’s a fair question and, ultimately, it’s the same issue as model collapse viewed from another angle. I don’t think the open web will stop being useful, but I do think the value will shift towards sources that are harder to synthesise.
When we think about original research and data, for example, they will continue to stand out in communities and forums where people describe direct experiences, rather than simply repeating someone else’s summary. Videos and other forms of organic social content, such as those published on TikTok and YouTube, will also become more important. This will be another challenge for brands, which will need to think about how to diversify their content and make their voices heard on platforms they could previously afford to ignore.
I expect the systems trained on this data to become more selective over time about where it comes from. Whether they will be able to give greater weight to verified, primary sources rather than treating all web content equally remains to be seen. It will be interesting to see whether all online content continues to be treated as equally useful.
Once again, this is good news for anyone actually producing something original rather than simply repackaging what is already available online.
Why rendering is the real game changer (and no one talks about it enough)
Well, what do you think? I told you this was going to be an interview you couldn’t miss!
Some really important insights from Nikki Halliwell.
And how can you disagree?
Rendering really is one of the most overlooked technical issues.
So many websites only make their important content available after JavaScript has “finished doing its job” in the browser. The result is that if a crawler doesn’t wait for that process, that content simply doesn’t exist as far as it’s concerned.
The same applies to infinite scrolling without numbered pages: everything beyond the initial load disappears from the view of many bots. And if content only opens after clicking, such as an accordion or a tab, a crawler that doesn’t click will never see it.
There’s also a simple but very common mistake: accidentally blocking, inside the robots.txt file, the JavaScript and CSS files needed to render the page correctly.
But as Nikki reminded us, you can actually check, step by step, whether your website is “readable” or not. You simply need to compare the rendered HTML with the raw HTML, try loading the page without JavaScript, and check loading times and log files.
The message is simple: if you want to be found and recommended by AI answer engines, first and foremost, your content needs to be genuinely accessible. Because tomorrow’s customers may discover your brand precisely this way.
A huge thank you to Nikki for her time and for such a practical and insightful conversation.
See you next Monday on SEO Confidential!